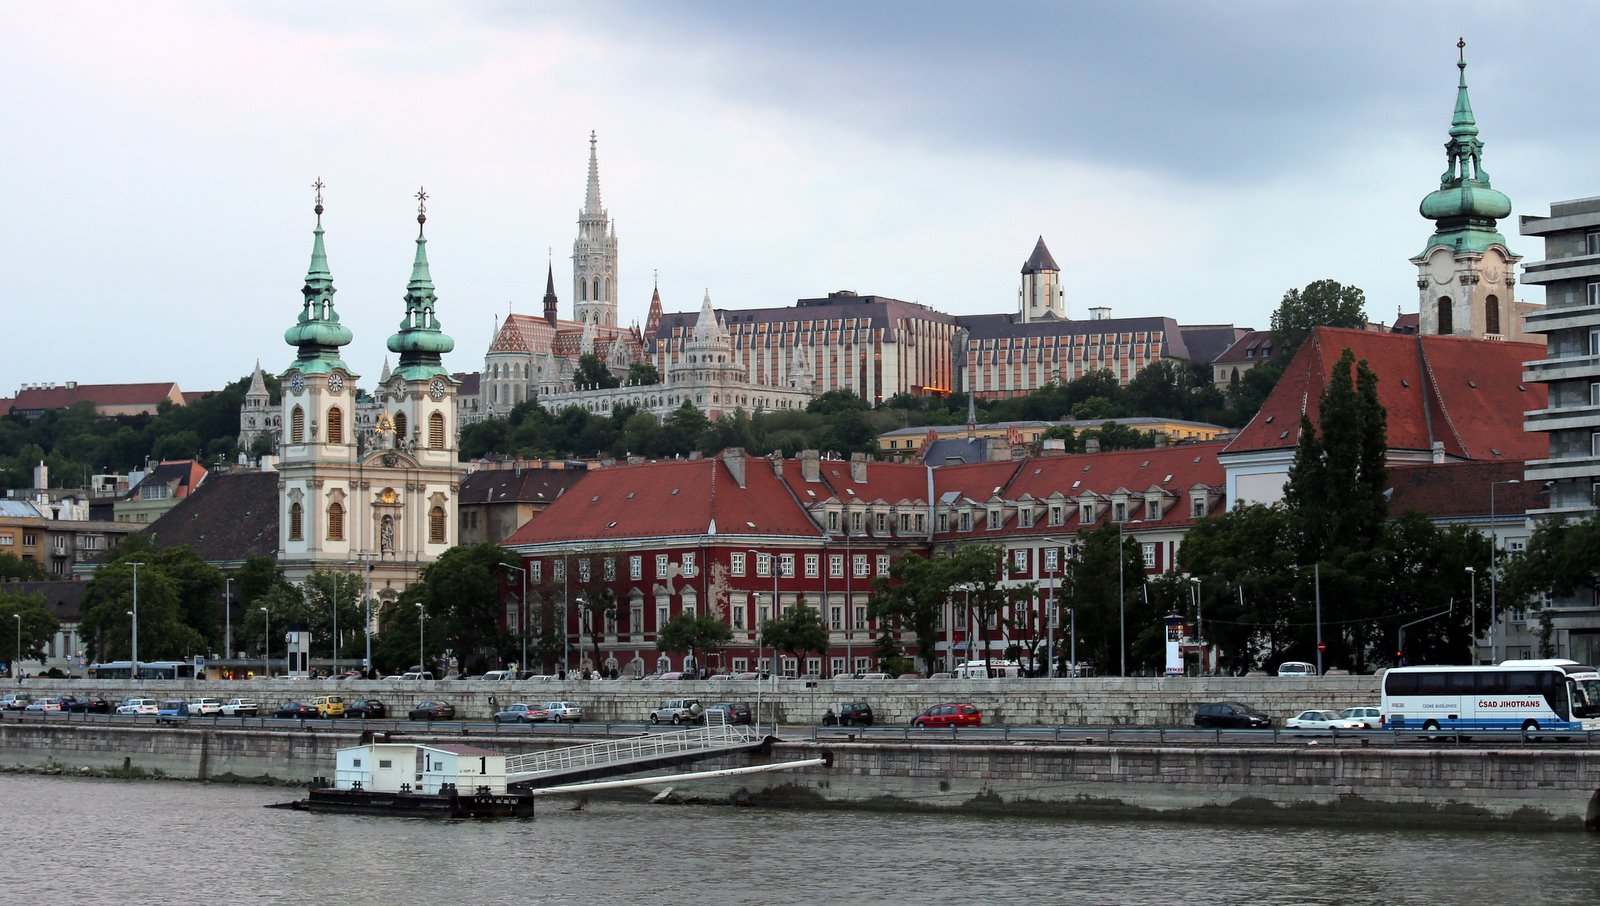
Felső-Víziváros and Matthias Church seen from the Danube
Felső-Víziváros és Mátyás-templom látványa a Dunáról · Thaler Tamas, Wikimedia Commons, CC BY-SA 3.0

13th Web-as-Corpus Workshop

Workshop @ EMNLP 2026 · Budapest, Hungary · 29 October 2026 · Room G6

The 13th edition of the Web-as-Corpus (WaC-13) workshop will be co-located with EMNLP 2026 in Budapest, Hungary. The workshop is endorsed by the SIGWAC ACL Special Interest Group in Web-as-Corpus, the Common Crawl Foundation, and the OpenEuroLLM project.
SIGWAC Common Crawl Foundation OpenEuroLLM

Call for Papers

Budapest, Hungary
Budapest, Hungary · Wilfredor, Wikimedia Commons, CC BY-SA 3.0

The World Wide Web has evolved from a resource for building linguistic corpora into the central data infrastructure powering modern natural language processing and Large Language Models (LLMs). As web-scale data increasingly shapes AI systems' knowledge and capabilities, understanding its quality, representativeness, and ethical implications has become critical.

At the same time, the "more is better" paradigm is being challenged by issues such as machine-generated content, data toxicity, limited metadata, and the under-representation of many languages and domains. These challenges call for a shift toward Data-Centric AI, focusing on the curation, analysis, and responsible use of web-derived data.

WaC-13 provides a multidisciplinary forum for research addressing the full lifecycle of web data. We invite submissions on methods, resources, and applications related to web corpora, with special emphasis on multilingual data and less-resourced languages.

Programme

Thursday 29 October 2026 · Room G6 · All times are Budapest local time (CET, UTC+1)

  1. 09:00–09:15
    Opening
  2. 09:15–10:30
    Keynote
    The Web as a Corpus and Common Crawl: A look back, forward and into present challenges
    Sebastian Nagel, Common Crawl Foundation
  3. 10:30–11:00
    Coffee break
  4. 11:00–12:30
    Oral session 1
    1. 11:00–11:20Long oral Wiktionary as a Crowdsourced Lexicon for English Dialectsremote
    2. 11:20–11:40Long oral Host-Aware Web Crawling for LLM Pretraining Data
    3. 11:40–11:55Short oral CHALIS: A Challenge Dataset for Language Identification in Difficult Scenarios
    4. 11:55–12:10Short oral You Can Tell Who’s Asking: What the Web’s Questions Are Made Of, and Who Made Themremote
    5. 12:10–12:30Long oral Segment-Level Register Analysis of the Multilingual Web
  5. 12:30–13:30
    Lunch break
  6. 13:30–14:00
    Virtual poster presentations
    1. 13:30–13:35Lightning talk Who Published This Headline? Editorial Fingerprinting in French News Under Topic Controlremote
    2. 13:35–13:40Recorded talk How Many Duplicates Are Left? Capture-Recapture and Sampling Inversion for Residual Duplication in FineWeb
    3. 13:40–13:45Lightning talk Auditing Source Exposure in Baidu and Google AI Searchremote
    4. 13:45–13:50Recorded talk Same Pages, Cleaner Labels: Language Identification for Eight Low-Resource Languages in mC4 and FineWeb-2
    5. 13:50–13:55Lightning talk Extraction Changes the Route: Main-Content Extraction and Language Identification in Web Corporaremote
    6. 13:55–14:00Lightning talk WiNCC: A Reproducible Pipeline for Constructing a Wikipedia-enriched Nepali Cross-lingual Corpusremote
  7. 14:00–15:30
    In-person poster session
    16 posters
    • A curated web-derived corpus of infant crying: Taxonomy, annotation, and ethical issues
    • A Taxonomy of Programming Languages for Code Generation
    • Can an Agent Debug a Web Corpus? Agentic Auditing of Slovak FineWeb2
    • CeyNews: A Sri Lankan Trilingual News Corpus
    • Counting Documents Is Not Counting Text: Unit Bias in Web-PDF Corpus Statistics
    • Is educational content enough? The linguistic and thematic effects of educational filtering
    • Keeping the Ums: Conversation-Analysis-Informed Verbatim ASR for Web Speech
    • Mapping Sámi languages in a Norwegian national web crawl: results from a representativeness study
    • PAWN++ in the Wild: Evaluating AI-Generated Text Detection on the Web
    • Probing Pretraining “Quality”: Sociolinguistic Mobility as a Lens on Web Corpus Filters
    • Task-Agnostic Web Document Annotation with LLM-Generated Descriptors
    • The Crawl Gap: Where Endangered-Language Web Content Is Lost Before It Reaches a Corpus
    • The CreateDebate Arguments Dataset: A Large-Scale Naturalistic Corpus for Computational Argumentation
    • Towards more reliable Web metadata: Do register classifiers learn register or genre features?
    • Using search engines to trace metalinguistic discussions of the noun “female” in digital discourse
    • What Persists across Web Crawls? Genre and News Topic Variation in South Slavic Web Corpora
  8. 15:30–16:00
    Coffee break
  9. 16:00–17:00
    Oral session 2
    1. 16:00–16:20Long oral RefinedGAW: A Refined German Academic Web Dataset
    2. 16:20–16:35Short oral Invisible on the Web: An Audit of Low-Resource Muskogean Languages in Web-Crawled Corpora
    3. 16:35–16:50Short oral HPLT3-PerRef: A Refined Large-Scale Persian Web Corpus via Supervised Document Quality Filtering
    4. 16:50–16:55Lightning talk Lost in Translation: Structured-Span Corruption in Machine-Translated Multilingual Web Corporaremote
    5. 16:55–17:00Recorded talk Whose Robots.txt? Consent-Infrastructure Inequality Across the Languages of Web Corpora
  10. 17:00–17:15
    Best paper award & wrap-up

Topics of Interest

Submissions are invited on (but not limited to):

Important Dates

(Hover over dates to see deltas)

  • Direct paper submission deadline 2026-08-15
  • Pre-reviewed ARR commitment deadline 2026-09-01
  • Review submission deadline 2026-09-07
  • Notification of acceptance 2026-09-10
  • Camera-ready paper due 2026-09-20
  • Workshop 2026-10-29T09:00+01:00
  • (October 29, 2026 at 9:00:00 AM Europe/Budapest)

All deadlines are 11:59 PM "Anywhere on Earth" (AoE, UTC−12).

  • Direct paper submission deadline August 15, 2026 at 11:59:59 PM AoE
  • Pre-reviewed ARR commitment deadline September 1, 2026 at 11:59:59 PM AoE
  • Review submission deadline September 7, 2026 at 11:59:59 PM AoE
  • Notification of acceptance September 10, 2026 at 11:59:59 PM AoE
  • Camera-ready paper due September 20, 2026 at 11:59:59 PM AoE
  • Workshop October 29, 2026 at 9:00:00 AM Europe/Budapest

Submission

We invite short (4 pages) and long (8 pages) papers. We allow for archival (to appear in the ACL Anthology) and non-archival submissions. Submissions should follow the ARR submission requirements. Following the ACL and ARR policies, there is no anonymity period requirement.

Paper submissions must use the official ACL style template. Please follow the paper formatting guidelines general to “*ACL” conferences. Authors may not modify these style files or use template designed for other conferences. The LaTeX style files are also available as an Overleaf template.

Submissions will be possible through ARR commitment and through direct submission via openreview.net

Workshop Organizers

Nikola Ljubešić
Jožef Stefan Institute, Slovenia
Yves Scherrer
University of Oslo, Norway
Laurie Burchell
Common Crawl Foundation
Veronika Laippala
University of Turku, Finland
Pedro Ortiz Suarez
Common Crawl Foundation
Vuk Dinić
Jožef Stefan Institute, Slovenia
Thom Vaughan
Common Crawl Foundation